VECTRA · silicon for private AI
Capable AI on hardware you control.
Every word an AI writes means reading its entire model from memory. VECTRA is custom silicon built around that fact, for organizations that run capable models on their own premises. A 27-billion-parameter model already runs on our prototype.
measured27Bparameters, Qwen3.8-27B
measured64 / 64layers on our accelerator
measured0output mismatches vs reference
measured313 mshardware time per token
The working prototype
Not a render. A 27B model answering from our hardware.
When a session is running, your question travels to the FPGA prototype in an AWS data center and the answer streams back word by word. When it isn't, replay the recorded run.
Checking whether a session is running.
A functional prototype, not the product: it answers at 2 to 3 words per second and reads your question first. Answers stop after about 70 words.
Recorded session · Build 32measured
0.0 sone real question, timed on the FPGA
reading
writing
0 s
FPGA timehost and networkprompt token read
FPGA time per word
- prompt
- 0
- reading
- 0 s
- words
- 0
- FPGA / word
- 0 ms
- host / word
- 0 ms
- total
- 0 s
A real question answered by the FPGA on 2026-10-26, replayed at the speed it ran.
The thesis
Private AI needs its own silicon.
More organizations want capable models running where their code, designs and records already live, with nothing sent to a cloud. What it costs to run a model there is set by one thing today's chips were not built around.
13.5GB
Read from memory for every single word a 27B model produces.
Measured from our packed model: 13.54 GB of 4-bit weights per token. The arithmetic is cheap. Moving those bytes is the cost, the power and the speed limit.
layer 1one tokenlayer 64 → next word
First application · our target
Private coding agents
Agents that read, change and test code on the team's own hardware, for organizations whose source cannot leave the building.
Alongside
Air-gapped and regulated sites
Defense, aerospace and financial teams that need a capable model with no outside connection.
Next
Autonomous machines
Vehicles, robots and field systems that need a large model inside a tight power budget.
Later
Private inference at scale
The same programmable core on faster memory, for enterprise and data-center deployments.
Where we start, and why customers would switch.
The first product is a board-level part for private AI computers. The design point is one organization running one capable model locally, where a data-center GPU is more machine than the job needs.
We are talking with design partners now to test that against real requirements: model quality, response time, power, cost and footprint. Our cost and power projections are shared with investors and partners.
Why VECTRA could win
Built around the bottleneck that actually matters.
Four decisions, each already exercised on hardware. Select one to see where it lives on the chip.
Memory interfaces: where the cost of every token is paidschematic, not to scale
Why can't NVIDIA, AMD or an established chip startup simply do this?
They could build almost anything, and their flagship GPUs are far faster than our part will be. Those products are built to serve many users at once in a data center, where large compute arrays and stacked memory dominate the cost. One organization running one capable model on its own premises is a different design point: memory bound, light on compute, priced like a component.
That segment is under-served. Winning it takes a streaming architecture, exact low-bit numerics and first-class support for hybrid models. We have that design running today. Our advantage is a verified implementation and the speed we move at, not a law of physics.
What is proven, and what is not
What we have measured, and what comes next.
FPGA validation proves the architecture works. It does not yet prove an economic advantage over GPUs. That is what silicon is for.
Proven
measured- A 27B model end to end on our FPGA architecture, all 64 layers
- Bit-exact against the reference on every output
- 313 ms of hardware time per token at 250 MHz
- Live answers from the hardware on this page
Next
in progress- Faster responses on the same FPGA
- Longer context for agent workloads
- Design partners with real requirements
- A processor core in silicon
The comparison
Where VECTRA fits.
Every option below can run a capable model. They differ in where your data goes, who the hardware is built for, and what it costs to own.
Cloud AI
No hardware to buy
The strongest models, but your code and data leave the building, and the cost grows with every request.
Flagship data-center GPUs
Fastest by far
Built to serve many users at once from a rack. Expensive and power hungry for one organization's model.
One PCIe GPU card · our baseline
40 tokens/s at 228 W
An NVIDIA L40S in a local server, running the same class of model, measured by us measured. Fast, but priced and powered for a data center.
VECTRA · our target
Built for one capable model
Private by design, reading speed for one user, at a fraction of the power and price of a GPU card projected.
The L40S figures are our own measurement with llama.cpp at 4-bit and nvidia-smi. VECTRA figures are projections from our ASIC model; investors and design partners can request the detailed numbers.
Path to silicon
From FPGA to a chip in partners' hands.
The plan our studies support. Process node, shuttle and tapeout timing are recommendations, not yet commitments.
Now
Prototype performance
Faster responses and longer context on the FPGA, measured against real agent workloads.
Next
Silicon team
An ASIC physical-design lead and a verification lead first, with a design-services partner for the backend.
Then
Core tile in silicon
A small core on a multi-project shuttle proves clock, power and function.
Then
First full chip
Core plus LPDDR5X memory interfaces, at 12 to 16 nm per our study.
Then
Boards with partners
Design partners' systems from the first silicon onward.
Why we can build it
A systems engineer's company.
The architecture, the RTL, the compiler, the runtime and the server were built by the founder, and every build, failure and measurement on the way is logged and dated.
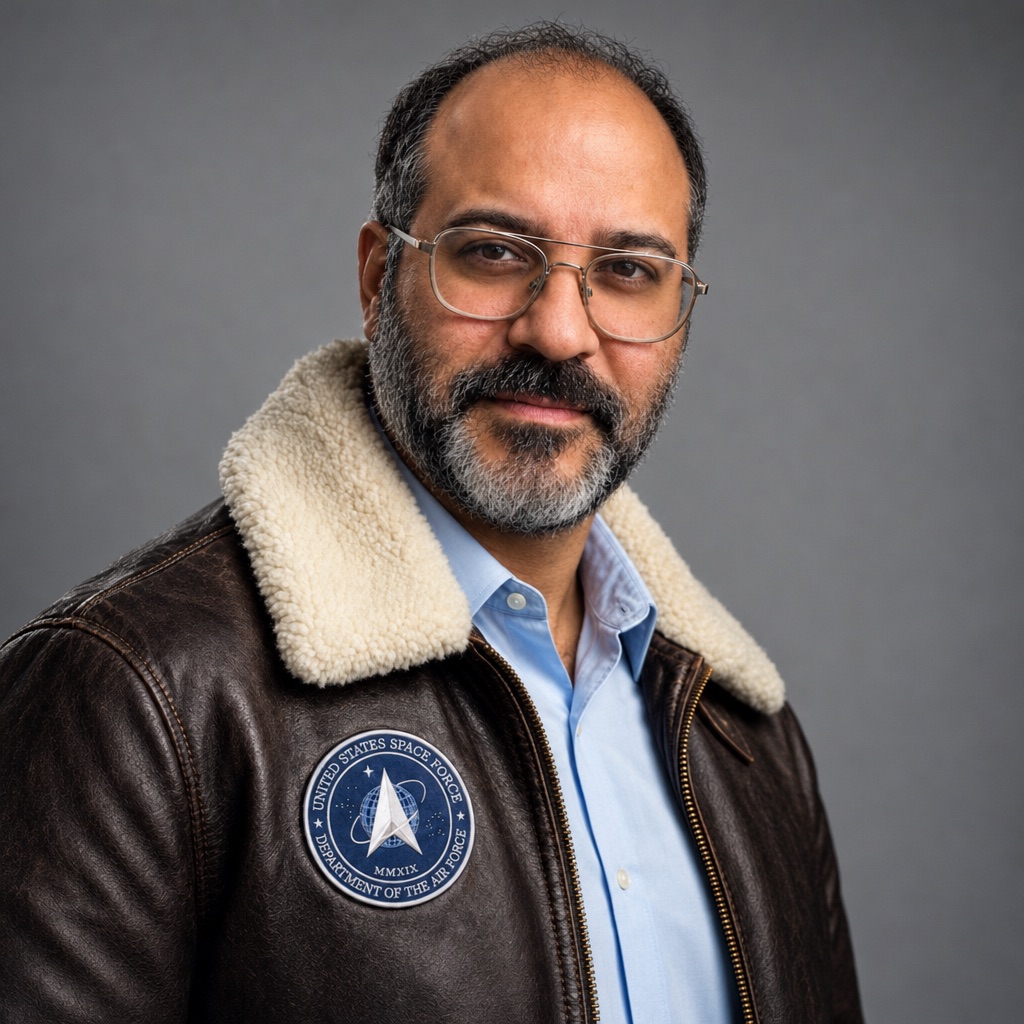
Jack Al-Kahwati
Founder · architect
From aerospace systems to AI silicon.
Jack has spent his career on complex aerospace and defense systems, including work on Boeing aircraft and Sikorsky helicopters, and on the software and hardware around them. He founded StarDrive Inc., where Valley Semiconductor began as an internal program.
He designed VECTRA and brought it from a numerics specification to a 27B model answering questions from FPGA hardware.
First hiresASIC physical-design lead and verification lead
Backend partnerDesign services for physical design, DFT and signoff
CustomersDesign partners with real power and cost targets
RecordA public, dated build log on the engineering page
Work with us
Help us take it to silicon.
Investors: the full case, milestones and capital plan. Product teams: become a design partner and shape the first part.